3Ci: Content Intelligence, LLM Caching & Secure Communication
A practical architecture for turning enterprise information into governed, searchable, contextual intelligence—connected to the systems that run the business.
General-reader edition · WaveUs Networks · September 2026
Executive overview
Organizations produce valuable knowledge across documents, databases, production systems, telemetry, tickets, engineering records, and collaboration tools. Yet information silos, inconsistent metadata, duplicated records, and access boundaries make it difficult to find the right evidence at the right moment. 3Ci—Content, Caching, and Communication—is a conceptual platform pattern that links three capabilities: deep content analytics, governed model context and caching, and secure integration with enterprise systems.
Core principle: AI should retrieve authorized, traceable evidence and use it to assist a workflow—not become an uncontrolled copy of the organization's source of truth.
1. Content: from raw information to useful signals
A content intelligence pipeline begins with source connectors and a controlled ingestion boundary. Connectors collect approved records from file repositories, ERP/MES systems, product lifecycle tools, service desks, application logs, and IoT platforms. Each source should retain its identity, owner, timestamp, access labels, retention policy, and provenance.
Processing stages
Ingest and normalize: parse PDFs, office files, tables, logs, events, and structured records. Normalize time zones, units, identifiers, and schemas.
Enrich: extract entities, topics, product IDs, work orders, fault codes, relationships, and document versions. Apply classification and sensitivity labels.
Index: maintain keyword, metadata, vector/semantic, and relational indexes as appropriate. Hybrid retrieval combines exact identifiers with semantic similarity.
Analyze: use SQL/OLAP, statistical analysis, time-series analytics, and anomaly detection to surface patterns, outliers, and operational correlations.
Observe: use Prometheus and OpenTelemetry for metrics and traces, Grafana for dashboards, and centralized logs such as Loki or an enterprise logging platform.
Grafana is commonly used to visualize metrics and operational signals; it is not itself a universal content-understanding engine. Themis can refer to different projects or products, so an implementation should specify the exact Themis component and its role—for example, policy, metadata, governance, or analytics integration—before committing to an architecture.
2. Caching: private LLMs, SLMs, and organizational context
In this architecture, “caching organizational data” does not mean copying every corporate record into a model's weights. A safer approach is to maintain governed external knowledge stores and supply relevant, authorized context at inference time. Frontier LLMs can handle complex synthesis, while smaller language models (SLMs) may support low-latency, on-premises, domain-specific, or cost-sensitive tasks.
Retrieval cache: cache embeddings, search results, or document fragments with tenant, role, source version, and authorization context.
Semantic response cache: reuse a prior answer only when the query, user entitlement, data freshness, model version, and policy context meet defined equivalence rules.
Prompt/context cache: optimize repeated system instructions and stable context where supported by the model provider, without placing secrets in client code.
Invalidation: expire or invalidate cached items when source content, permissions, retention status, or policy changes.
Audit: record model route, prompt template version, source references, cache hit/miss, evaluation status, and policy decisions while minimizing sensitive payload logging.
3. Communication: connecting the enterprise safely
Communication is the integration plane between AI services and business operations. Typical adapters connect ERP for orders and inventory; MES for routing and production state; IoT gateways for telemetry; private Wi-Fi and network management for connectivity signals; and identity or security systems for access and incident workflows.
Prefer versioned APIs, event-driven messaging, mutual TLS, OAuth 2.0/OIDC, short-lived credentials, scoped service identities, schema validation, idempotency keys, and explicit rate limits. Place connectors behind an API gateway or integration service, and keep secrets in a managed secret store. Avoid giving a language model direct, unrestricted database or device access.
4. Reference deployment and governance
A representative deployment separates user experience, identity, API gateway, orchestration, retrieval, model serving, data stores, integration adapters, and observability. Sensitive workloads may run in a private cloud or customer-controlled environment. Data residency, model-provider retention, encryption, backup, disaster recovery, and deletion requirements should be assessed for each data class.
5. Outcomes and success measures
Search success rate, time-to-find, and citation coverage for knowledge tasks.
Answer groundedness and unsupported-claim rate using a maintained evaluation set.
Latency, cache hit ratio, cost per successful task, and model-routing distribution.
Connector reliability, freshness lag, authorization failures, and audit completeness.
Operational impact such as reduced ticket resolution time or fewer repeated investigations.
Implementation note: Begin with one bounded workflow and a curated knowledge domain. Establish data ownership, permissions, evaluation criteria, and rollback before expanding model access or autonomous actions.
Conclusion
3Ci is most useful when content analytics, model context, and system integration are designed as one governed lifecycle. The result is not merely a chatbot; it is an observable knowledge service that supports people and business processes with evidence, access control, and operational feedback.
Executive perspective
3Ci combines Content intelligence, Caching and Communication into an enterprise architecture that makes operational knowledge discoverable, reusable and actionable while retaining control over data access and provenance.
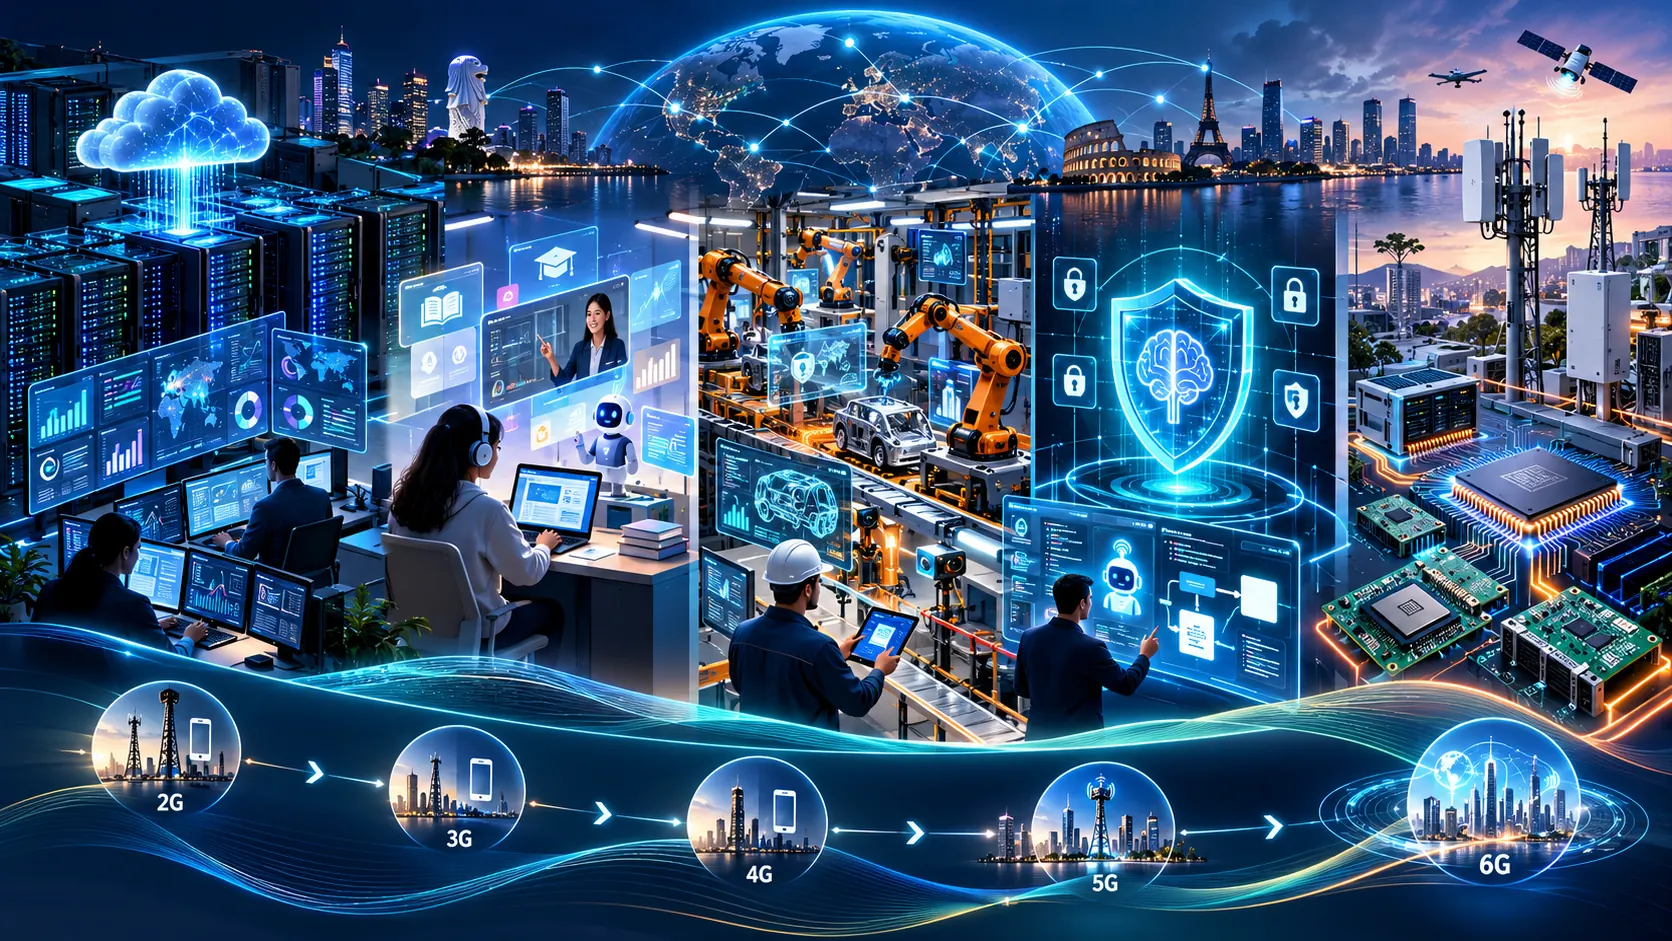
Illustrative conceptual trend to explain a migration or operating pattern. Values are normalized examples, not measured market forecasts or customer results.High-level conceptual progression. Dates indicate broad industry eras or planning horizons, not universal deployment dates.
1. Content intelligence and observability
An enterprise content plane ingests structured and unstructured data from ERP, MES, PLM, CRM, document repositories, service tickets, telemetry and engineering systems. A connector layer normalizes metadata, timestamps, tenant, business unit, retention class, sensitivity label and source lineage before content is indexed. Parsing pipelines handle PDF, office documents, tables, scanned documents (OCR), images, audio transcripts, logs and time-series streams. Chunking should respect semantic boundaries such as document headings, work-order steps, BOM hierarchy, alarms and software versions rather than using a single fixed token window.
A governed analytics stack can combine OpenTelemetry for traces and metrics, Prometheus for time-series metrics, Grafana for dashboards, Loki for logs, Tempo for distributed traces, OpenSearch for full-text search, Apache Kafka for event streaming, dbt or Spark for transformations, and a lakehouse/object store for historical evidence. Themis is included as an example of a policy, authorization or data-governance component where selected and validated for the deployment; its exact role must be matched to the chosen Themis project/product and integration contract. Data quality controls include schema validation, deduplication, clock alignment, source freshness, missing-field detection, drift monitoring and lineage retention.
2. Retrieval, caching and frontier/SLM orchestration
A practical RAG request path includes identity assertion, policy decision, query normalization, cache lookup, retrieval, reranking, model selection, response validation and auditable delivery. Separate caches should be used for exact-response caching, semantic retrieval caching, embedding/model artifact caching and frequently accessed source fragments. Cache keys should include tenant, authorization scope, model/version, prompt-template version, corpus/index version, locale and relevant policy context. Never share a cached answer across users or roles unless authorization equivalence is established at cache-read time.
Frontier models can be routed to complex reasoning, cross-document synthesis or high-risk tasks; small language models (SLMs) can handle classification, extraction, routing, summarization and low-latency on-premise tasks. Model routing should be based on task complexity, quality thresholds, latency budgets, data residency and cost controls—not model size alone. Invalidation triggers include source updates, ACL changes, revoked documents, model updates, policy changes and time-to-live expiration. Sensitive prompts and outputs require encryption, least-privilege access, retention controls and redaction policies.
3. Communication fabric and enterprise integration
Adapters connect ERP and manufacturing systems through supported APIs, event streams or controlled database views; shop-floor connectivity may include OPC UA, MQTT, Modbus gateways and vendor-specific interfaces, subject to OT segmentation and safety review. Private Wi-Fi and private 5G provide wireless access for handheld scanners, AGVs, cameras, tablets and industrial sensors. Security integration may consume SIEM/SOAR events, identity provider claims, access-control events and physical-security alerts.
Use an API gateway and service mesh for authentication, rate limits, schema validation, mTLS, service identity and observability. Use store-and-forward queues for intermittent plant connectivity and idempotent event processing to avoid duplicate work orders. OT-to-IT data flows should be explicitly allow-listed, unidirectional where appropriate, and governed by change management. The integration contract should define ownership, data semantics, latency/SLA, retry behavior, versioning and failure-mode behavior.
4. Metrics and operational analytics
Useful metrics include content freshness, ingestion lag, source coverage, retrieval precision/recall, citation coverage, answer acceptance, cache hit ratio, cache staleness incidents, p50/p95/p99 response latency, model cost per resolved task, policy denials, data leakage test results and connector error budgets. Grafana dashboards should expose both business outcomes—time to locate a procedure, first-time resolution and work-order cycle time—and system health—queue depth, GPU utilization, token throughput, error budgets and index lag.
5. Business trend and migration path
Enterprises are moving from keyword search and isolated BI dashboards toward governed data products, semantic retrieval and workflow-integrated copilots. The commercial shift is from generic chat interfaces to domain-specific assistants connected to systems of record, with measurable outcomes, tenant isolation and auditable controls. Adoption commonly progresses from read-only search, to analyst copilots, to approved workflow suggestions, and only then to bounded write actions with human approval.
Implementation roadmap and decision gates
Discover: define outcomes, stakeholders, baseline KPIs, data classification, constraints and system owners.
Architect: document trust boundaries, interfaces, data contracts, availability targets, failure modes and operating responsibilities.
Pilot: select a bounded use case, create a representative test set, capture baseline and compare measured outcomes against agreed acceptance criteria.
Validate: conduct security, privacy, accessibility/safety, performance, reliability and user acceptance testing as applicable.
Scale and sustain: version models/configuration, monitor drift and incidents, manage changes, train users and maintain rollback/exit plans.
Frameworks and standards evolve. Confirm the applicable edition, jurisdiction, product scope and contractual obligations before using this paper as a compliance basis.
Market outlook: enterprise AI is shifting toward governed deployment
Gartner's September 2026 outlook forecasts worldwide AI spending of $2.67 trillion in 2026 and $3.64 trillion in 2027. Gartner also highlights agentic features embedded in existing enterprise software and workflow automation. The OECD's 2026 analysis emphasizes market concentration in compute, cloud and data, while noting that open-source ecosystems can lower entry barriers. For 3Ci, this points to customer needs around model choice, data sovereignty, auditable retrieval, cost governance and integration with systems of record—not just a chat interface.
Gartner forecasts $2.67T worldwide AI spending in 2026 and $3.64T in 2027. These are market-wide forecasts, not addressable revenue estimates for WaveUs. Forecasts can be revised.
Analysis of AI competition, compute/data concentration and open-source effects
Policy and market-structure analysis, not a revenue forecast.
Market data and forecasts are paraphrased from publicly accessible source publications and independently visualized here. No third-party charts, tables, report prose or proprietary graphics are reproduced. Forecasts reflect source publication dates and may change. Market categories overlap and must not be added together without reviewing each methodology.
Reference interfaces and data contracts
Layer
Example interfaces
Minimum contract / evidence
Source adapters
REST/GraphQL, vendor ERP/MES APIs, JDBC read views, Kafka events, OPC UA/MQTT via OT gateway
Interface names are examples for architecture planning. Validate protocol versions, vendor support, security profiles and interoperability against the actual system under test.
WaveUs positioning: systems engineering through deployment
WaveUs's stated engineering positioning spans wireless systems, cloud-native RAN/DAS, network APIs, AI-RAN and global telecom deployments. Applied to 3Ci, this creates a systems-integration proposition: connect enterprise knowledge and analytics to operational networks, edge infrastructure and existing enterprise systems, with lifecycle engineering rather than a stand-alone chatbot.
Positioning is based on company-provided profile information. Specific customer results, deployment counts, certifications and performance outcomes should only be published with substantiation and authorization.